CEM
3D Electromagnetics
Eigenmodes of an 8-Qubit Superconducting Chip
A Frequency-Laddered Transmon Array, Solved with the Palace Finite-Element Solver
Explore GPU-accelerated computational electromagnetics (CEM) powered by NumericalAI and the open-source Palace 3D finite-element solver. Designing a quantum processor means knowing — before fabrication — exactly where each qubit will resonate. An eigenmode analysis finds those natural frequencies and field patterns directly from the layout, no drive signal required, by solving the source-free curl-curl eigenproblem.
This example models an 8-qubit superconducting array whose junctions are deliberately frequency-laddered: each qubit's Josephson junction is a lumped inductor–capacitor (LC) port with a slightly different inductance, spacing the qubits across a frequency comb to avoid collisions. Palace computes the collective, hybridized modes of the whole array near the transmon operating band — a full-wave picture of how energy distributes across the chip and how neighbouring qubits couple.
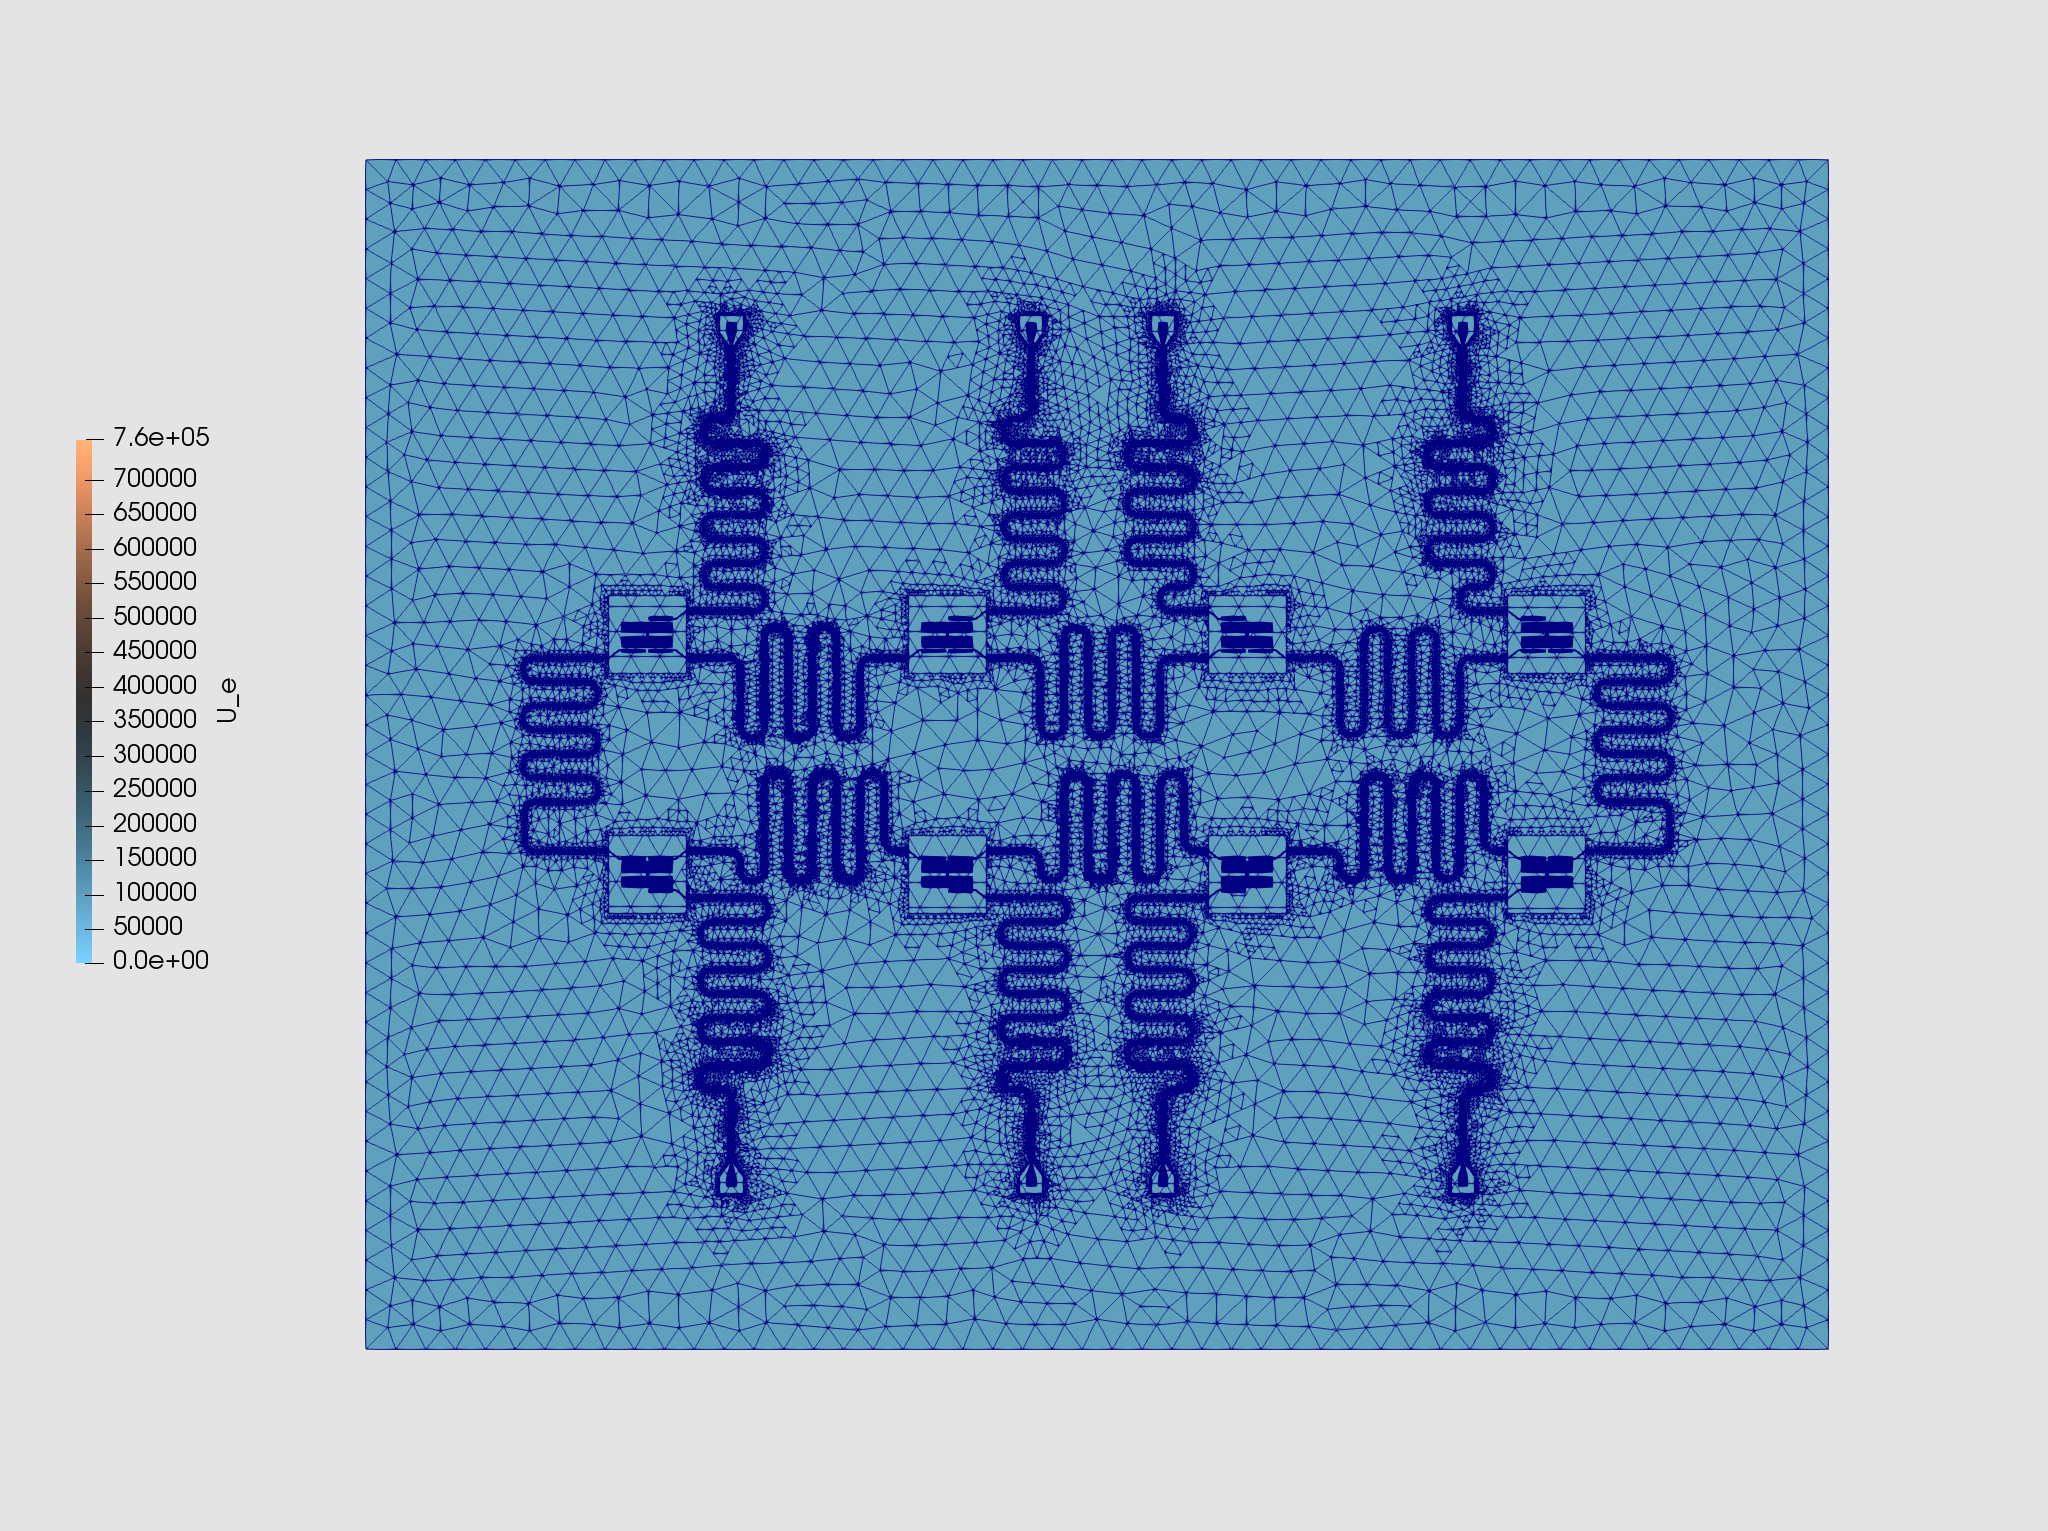
Electric energy density (U_e) of a computed eigenmode across the 8-qubit array, on the meshed chip — energy localizes on individual qubits and spills into their neighbours.
What the Model Represents
Qubits as Lumped LC Ports
Eight lumped ports stand in for the Josephson junctions of the qubits. Each is a linearized junction: an inductance stepped from 14.5 nH down to 11.0 nH in 0.5 nH increments, shunted by a fixed capacitance C = 2.0 fF, oriented along +Y across the junction gap. In the small-signal (linear) limit this is exactly how a transmon presents itself to the surrounding electromagnetic environment.
A Detuned, Coupled Array
Because all eight ports share the same chip, the eigensolver returns the hybridized modes of the full array. The laddered inductances spread the bare qubit frequencies into a comb, while the electromagnetic environment still couples neighbours — so the computed spectrum reveals both the intended detuning and the residual hybridization that governs gate performance and crosstalk.
Simulation Configuration
Geometry & Mesh
Structure:
8-qubit QPU array
Qubit ports:
8 lumped LC
Length unit:
µm (L₀ = 1e-6)
Mesh:
Tetrahedral + AMR
Element order:
1
Substrate
Permittivity εᵣ:
11.9 (silicon-like)
Anisotropy:
Isotropic
Loss tangent:
0 (lossless idealization)
Permeability µᵣ:
1.0
Vacuum region:
εᵣ = µᵣ = 1.0
Solver
Problem type:
Eigenmode
Eigenpairs:
20
Target:
4.0 GHz
Inner solver:
FGMRES + multigrid
Tolerance:
1e-8
Boundary Conditions
Lumped ports (×8):
L = 14.5 → 11.0 nH (0.5 nH steps), C = 2.0 fF, direction +Y
Metal:
PEC (superconducting electrodes & ground)
Refinement:
Adaptive (AMR), up to 5 iterations, nonconformal
Computational Setup
8
Qubit LC Ports
20
Modes near 4 GHz
AMR
Adaptive Mesh
GPU
Cloud Compute
Junction & Material Parameters
| Parameter | Value | Role |
|---|---|---|
| Junction inductance L | 14.5 → 11.0 nH | Laddered per qubit to set a frequency comb |
| Inductance step | 0.5 nH | Uniform detuning between neighbouring qubits |
| Shunt capacitance C | 2.0 fF | Fixed across all eight junctions |
| Substrate εᵣ | 11.9 | High-permittivity (silicon-like) dielectric |
| Loss tangent tan δ | 0 | Lossless idealization — frequencies only |
| Number of qubit ports | 8 | Size of the coupled array |
The lumped L and C linearize each Josephson junction; stepping L from 14.5 nH down to 11.0 nH gives each qubit a distinct bare frequency, and the solver targets the 20 lowest modes near 4 GHz, the operating band of transmon qubits. The substrate is modeled as lossless here, so this run reports frequencies and field patterns rather than dielectric-limited quality factors.
Reading the Physics
Frequency Laddering Prevents Collisions
Stepping the junction inductance across the array spreads the bare qubit frequencies into a comb. This is a deliberate design choice: two qubits that land on the same frequency hybridize strongly and become impossible to address independently. By solving the full array as one eigenproblem, the simulation shows the actual, coupledspectrum — confirming the intended detuning survives the electromagnetic environment, and flagging any residual near-degeneracies before tape-out.
Adaptive Mesh Refinement & Multigrid
Rather than guess a mesh density up front, this run uses adaptive mesh refinement: Palace estimates the discretization error, refines where the fields vary sharpest (around the junction gaps and electrode edges), and repeats for up to five nonconformal iterations. Paired with a geometric-multigrid-preconditioned FGMRES solver on GPUs, it converges the 20 target eigenpairs to a tight 1e-8 tolerance while keeping the element count where it actually matters.
Where This Applies
Quantum Processor Design
Predict qubit frequencies of a full chip layout before fabrication, and catch frequency collisions early in the design cycle.
Detuning & Crosstalk
Verify that a laddered frequency plan survives real coupling, and quantify how neighbouring qubits hybridize across the array.
Mesh & Convergence Studies
Use adaptive refinement to converge mode frequencies without hand-tuning the mesh, and document the error at each refinement level.
Readout & Resonators
Extend the same eigenmode workflow to readout resonators, Purcell filters, and bus cavities that share the chip with the qubits.
Why NumericalAI for Quantum Hardware
Powered by Palace — AWS's open-source, GPU-accelerated 3D finite-element solver for full-wave electromagnetics
Lumped-port junctions — model each transmon as an LC element, with per-qubit inductances for a full frequency plan
Adaptive mesh refinement — converge mode frequencies automatically, refining only where the fields demand it
Multigrid on GPUs — geometric-multigrid-preconditioned FGMRES resolves the full coupled spectrum on cloud compute
Business Value & ROI
NumericalAI brings production-grade electromagnetic simulation to an intuitive cloud interface — no solver installation, no cluster administration, no meshing bottleneck.
Tape out with confidence: verify the frequency plan and coupling across a full 8-qubit chip in a single adaptive GPU run, catching costly frequency collisions before a wafer is ever fabricated.
Ready to Model Your QPU?
Run full-wave eigenmode simulations of superconducting qubit chips with Palace on NumericalAI. Upload your Palace config.json and mesh, and get mode frequencies and field maps on cloud GPUs.
AI-Assisted GPU-Powered Simulations
© 2026 NumericalAI, all rights reserved. |Privacy Policy |Terms of Service |Executive brief |CEM vs HFSS |FAQ